I find myself thinking about this a lot lately, and it's not really a new problem.
Traditionally in software development you might be producing a REST API probably targeting a particular use case:
- Backend to a web site
- Backend to a mobile app
- A generic API for a 3rd party to consume
And if you've built one of those you can probably then go on and use it for one of the others, but in my experience you will find that although you can make it work there will be compromises. Arguably the most successful software I've personally ever worked on was a website API that found use as a generic API, but it was forever slightly awkward because of it.
Then along came Model Context Protocol (MCP), for the uninitiated the 'generic' API standard that LLMs can use for tools / prompts etc.
In the homelab space you can probably pick any self hosted application and google* up an MCP server for it that someone has made. Commonly what you'll find is a well meaning attempt to translate a REST API into an MCP server. A decent LLM will probably manage to do most tasks, but it's going to be slow. Multiple rounds of back and forth between calls to explore lists, gather Ids to make further calls and eventually do the requested action. That's ignoring the issue that if you're using it over voice, your search is probably not coping with transcript errors.
It'll work, just about. But if you want a good MCP experience, where you're not waiting around a lot then it needs more thought.
Our home lab set up is mostly centered around 2 things, Home Assistant and Lyrion Music Server, and while Music Assistant is a thing it doesn't quite cover our use cases so Lyrion has stayed pretty firmly entrenched. This means that music control, one of the best uses for voice assistants, isn't really a 'free' thing for us.
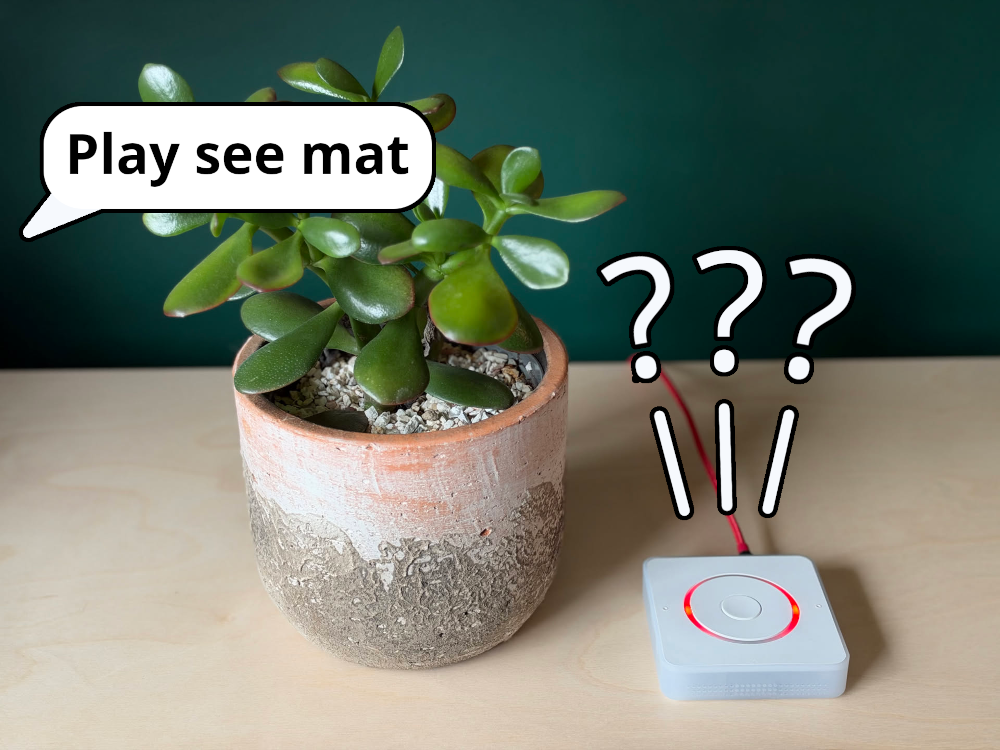
So I thought I'd write an MCP server for LMS, then I found there were a few out there already so used one of those, and immediately started to run into problems. "CMAT" got transcribed as "see mat", asking for "Pet Shop Boys" got you the same tracks every time, and it was slow.
You will be unsurprised to hear that I went back to the plan of building my own, but armed with some experience from the MCP server on my BoardOil project, and a new problem of 'voice'.
I knew it needed a small number of tools, very aimed at the things I wanted the LLM to do:
- "Play 90s pop."
- "Play the live album by [artist], I can't remember the title."
- "Append top-rated [artist] tracks to the current queue."
- "Play the original album version of the live track currently playing."
Going into it I didn't know how to solve the transcription problem but suspected it involved building the MCP server's own index.
And so was born Lyrion Voice MCP.
It supports an agent searching, browsing and controlling the players - that's it.
Its search tool returns something more like you'd expect to get back on a Spotify search rather than a plain result list (they've basically nailed solving this problem - try their search with typos and it's still very good).
Here's an (abbreviated) result for a search of 'Hurts'
{
  "artists": [
    {
      "name": "Hurts",
      "browseRef": "artist_accabe28a29e7a3a"
    }
  ],
  "albums": [
    {
      "title": "Desire",
      "artist": "Hurts",
      "browseRef": "album_c0e9b94e66bb3637",
      "playRef": "album_c0e9b94e66bb3637"
    },
    --snip--
  ],
  "topTracks": [
    {
      "title": "Heart",
      "artist": "Pet Shop Boys",
      "album": "Actually",
      "rating": 4,
      "playRef": "track_f5d79d180a9f2c4f"
    },
    {
      "title": "The Water",
      "artist": "Hurts",
      "album": "Happiness (Deluxe Edition)",
      "rating": 5,
      "playRef": "track_a045435279d61820"
    }
    --snip--
  ],
  "tracks": [
    {
      "title": "Hurt",
      "artist": "Nine Inch Nails",
      "album": "The Downward Spiral",
      "rating": 0,
      "playRef": "track_e5e08a09ccb079dd"
    },
    {
      "title": "Heart",
      "artist": "Pet Shop Boys",
      "album": "PopArt - The Hits",
      "rating": 0,
      "playRef": "track_c62702a60955ebaa"
    },
    {
      "title": "Wait Up",
      "artist": "Hurts",
      "album": "Desire",
      "rating": 0,
      "playRef": "track_fe9c2761708e2591"
    },
    --snip--
  ],
  --snip--
}
There's quite a bit to unpack here and I've shortened the results a bit to save your mental tokens.
playRef and browseRef are tokens the agent can use to... play and browse via other endpoints.
The search index has successfully matched 'hurts' to the correct artist, and returns album matches. But in the other results you can see the fuzzy matching coming in, PSB's 'Heart' is close enough to be included in the top tracks and the index is happy to match without the 's', giving 'hurt' results. This leaves it up to the LLM to make the final call on what it's going to play - it probably has more context in the request, eg "play music by hurts" which will steer it in the right direction of the artist.
So what's the index doing? Let's take a slightly more interesting example 'CMAT'. She gets indexed something like this:
| Representation | Value |
|---|---|
| Original | CMAT |
| Normalised / compact | cmat |
| Word token | cmat |
| Consonant skeleton | kmt |
| Double Metaphone | KMT |
| Three-character fragments | cma, mat |
| First letter spoken, remainder literal | seemat |
| Every letter spoken | seemaytee |
That's roughly what goes into the index, and then the same transformations are applied to the search term too, so if the speech to text gave us 'see mat' you can see how it would now strongly match. Each of these came from trying different matching approaches suggested by the LLM. I then assessed each against a big sample of transcribed searches and picked the best performing ones.
Another common problem is number equivalence, this is handled by 'VI', 'six', and '6' all getting indexed as 'number 6'.
Top rated tracks and general matches are then returned separately, and a random seed is used to select different tracks each time from large pools of matches, so I'm not stuck listening to the same 10 Pet Shop Boys tracks every time.
The first few attempts worked surprisingly well, although there was an amusing evening on the sofa with the husband trying to get it to play all the weirdly spelled artists, and me trying to patch it up to work.
Long term some niggles came to light, the most interesting being needing special handling for self titled albums, otherwise they never ranked high enough in the results.
The LLM itself still needs a bit of guidance about building playlists (mix top tracks and good matches) otherwise you only ever get 5 star tracks, which is boring.
This all adds up to a pretty decent experience which I've been really happy with, the agent can find the music I want often with 1 tool call, sometimes 2 if there's a follow up browse. With a plain translation of the API (and Lyrion's API is... eccentric to say the least) I wouldn't get anything like this performance.
So, want to build a good MCP server?
- Evaluate existing solutions.
- Establish your use cases.
- Assess available technologies.
- Do actual testing.
Sounds suspiciously like normal software engineering, it's almost like the LLM malarkey isn't as different as people make out.
My Lyrion Voice MCP server is available up on GitHub.
*Other search engines are advised at this point.